Speaker Dataset Creation
Module Description
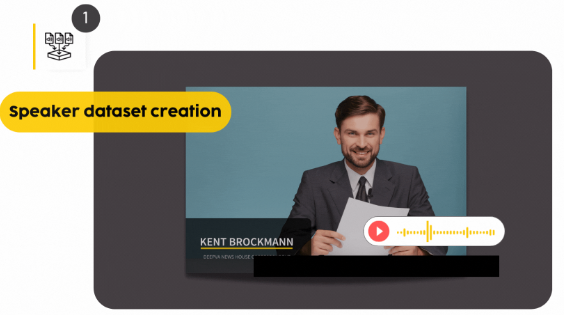
Speaker Dataset Creation reads the names displayed on screen text-inserts and associates them to the corresponding person. Create an individual and unique dataset of your own repository of personalities for audio-based datasets.
Module ID: speaker_dataset_creation
Module Parameters
| Name | Type | Default | Description |
|---|---|---|---|
| dataset_id | string | null | The dataset ID to store the extracted voices (See Dataset Resource). |
| detect_single_name | boolean | false | Speaker Dataset Creation is optimized on detecting full names. Enable this to detect single names as well. |
| apply_generic | boolean | true | Use the generic method to find names |
| name_dictionary_list | List of strings | null | You can provide a custom names dictionary to detect your custom names. Only names from this list will be detected. Example: ["Angela Merkel", "Markus Söder"] |
| min_face_size | integer | 112 | Minimum size of the smallest side of the face in pixels |
| sharpness_threshold | integer | 40 | Minimum quality of the face (lower number is more blurry) |
| offset_start | number | 0 | Additional audio extracted as a voice sample from the beginning of the detection in seconds. |
| offset_end | number | 0 | Additional audio extracted as a voice sample from the ending of the detection in seconds. |
| segment_merge_threshold | number | 1 | Segments will be merged if the gap between voice segments is lower than this threshold in seconds. |
| name_heuristic | string | v1 | Method used to detect names in the lower thirds. Possible values are: v1 (classic method), v2 (line-based detection with higher accuracy; supports hyphenated and multi-part names, academic titles and party affiliations after the name, and ignores headlines, credits and text in the scene). |
| allow_unknown_surnames | boolean | false | Only with name_heuristic v2: also detect names whose surname is not contained in the name dictionaries, if the layout of the lower third clearly identifies the name. Detects more names, but may add false detections. |
| max_text_tilt | number | 2.0 | Only with name_heuristic v2: maximum tilt of the name text in degrees (range from 0 to 90). More tilted text is treated as text in the scene (e.g. name plates or signs) and ignored. Increase the value if your lower thirds are slightly rotated or animated. |
| min_text_height | number | 0 | Only with name_heuristic v2: minimum height of the name text in percent of the frame height (range from 0 to 100). Smaller text, e.g. captions or text in the scene, is ignored. 0 disables this filter. |
| extract_subtitle | boolean | false | Add the text directly below the detected name, usually the role or function of the person (e.g. Spokesperson of the Federal Government), to the result as field subtitle. Works with both values of name_heuristic. |
| multi_line_subtitle | boolean | false | Only with extract_subtitle: also include further lines below the first subtitle line, separated by commas. Can include unrelated text directly below the lower third, such as channel logos. |
Example
Send the following JSON as request body via POST to the /jobs/ endpoint:
{
  "sources": [
    "{url-to-your-image}"
  ],
  "modules": {
    "speaker_dataset_creation": {
      "dataset_id": "{ID-of-your-dataset}"
    }
  }
}